Swasthya Sarathi
A healthcare-companion platform for Swasthya Sarathi
A website and mobile app development project for a multi-service healthcare companion — It helps peo...
Read itLLM systems, RAG and applied ML
AI features built with care, not just for demos. Tests before launch, answers based on real sources with citations, guards against made-up answers, and a cost-per-request budget you can watch.
Last updated
The most valuable thing we do on an AI engagement is sometimes to tell you not to build one.
A regex will beat an LLM at extracting a GSTIN. A trained classifier will beat an LLM at sending a support ticket to the right place, at a thousandth of the cost and a hundredth of the delay. A SQL query will beat an LLM at "how many orders shipped late last month" — and it will be right, which the LLM will not always be. If the task has one fixed answer, a fixed-rule system should give it. LLMs are for language: summarising, drafting, pulling facts from messy text, talking with people, and working through documents where the rules cannot be written down.
When it is truly the right tool, we build it with care, not just as a demo. That means an evaluation harness before anything goes live. It means guards that catch a made-up answer before your customer reads it. It means a retrieval layer that bases every answer on a source you can cite. And it means a cost-per-request budget you really watch. The demo is the easy part — anyone can produce an impressive one in a weekend. Making it correct on the four hundredth query, at a cost per query you can justify, is the real work.
If you cannot measure whether your AI feature got better or worse, you are not engineering. You are gambling.
So the first thing we make on every AI project is not a prompt. It is an evaluation set: 150 to 400 real inputs from your own field, each with a known-good answer, put together with your experts. It costs a week and it is the most valuable week in the project.
The harness runs that set on every change, such as a new prompt, a new model version or a new way of fetching text. It scores each one. Where there is a right answer, it checks for an exact match. Where there is not, it checks how closely the answer follows the fetched source. A stronger model also grades answers against a rubric, with human spot-checks. It also records delay at p50 and p95 and cost per request. It runs in CI, just like a test suite, because that is what it is.
The value shows up the first time somebody says "let us just tweak the prompt". Without a harness, that is a guess. With one, you find out in four minutes that the tweak fixed three cases and quietly broke eleven. We have watched more than one team ship a "small prompt improvement" that dropped accuracy nine points. They only found out from customer complaints two weeks later.
We have been called in to fix all six of these. Five of them can be avoided in week one.
No eval set, no starting score, no pass mark. Every prompt change is a guess, and a "small improvement" quietly dropped accuracy nine points two weeks ago.
Asked about a refund window that does not exist, it makes one up in smooth, believable English. There is no way to refuse, so refusing was never an option for it.
Twenty fetched chunks stuffed into every prompt, the top model used on every request including "hi", and no saving of answers. ₹3 lakh a month for something a reranker and a router would have run for ₹40,000.
Three model calls one after another and a slow vector search. Users leave the chat and open a support ticket, which was exactly what this was meant to prevent.
Documents cut blindly every 500 characters, splitting tables and clauses in half. The model is not hallucinating. It is faithfully summarising garbage.
PII in prompts, sent to a consumer API tier, with no data processing agreement and nothing hidden. The DPDP question arrives and there is no honest answer.
| Classic ML / rules | Prompt + RAG | Fine-tuning | |
|---|---|---|---|
| Answer lives in your documents | No | Best | Poor — and goes stale |
| Task is deterministic (extract, route, count) | Best | Wasteful | Wasteful |
| Needs a consistent tone or output format | No | Workable | Best |
| Cost per request | Negligible | Moderate | Low, after training |
| Answers must be citable | n/a | Yes | No |
| Updates when your data changes | Retrain | Instantly | Retrain |
| Typical time to production | 3–6 weeks | 6–12 weeks | 10–16 weeks |
None of this shows in the demo. All of it is what separates a feature you can stand behind from one you will have to apologise for.
150–400 real inputs with known-good answers, scored on accuracy, following the source, correct refusals, delay and cost. Runs on every prompt and model change. If results get worse, the build fails.
Answers based only on the fetched text. Claims checked against the source chunks. A clear "I do not know" path that passes the question to a human, because a system that cannot refuse will always make things up.
Cutting text by meaning so tables and clauses stay whole, search by both keyword and vector, a reranker, and citations the user can open. Most "hallucination" is a retrieval bug in disguise.
Routing by difficulty: a cheap model for the easy 80%, and the top model only where it is worth it. Prompt caching, context sizing, streaming. Cost per request is tracked with an alert for odd spikes.
PII hidden before data leaves, business API tiers that keep your data out of training, full logs of prompts and answers, and open-weight models in your own VPC where DPDP or a contract demands it.
Every request is traced with its fetched text, tokens, cost and delay. Thumbs-down feedback goes into the eval set, so live failures become tomorrow's tests.
The order is the whole method. Teams that build first and measure later launch systems that are wrong with full confidence.
What is the task, what does success look like in numbers, what does a wrong answer cost, and is a model even the right tool? This is where we tell you a classifier or a SQL query does the job for a hundredth of the price. Several of our best AI projects ended here, and those clients came back.
150 to 400 real inputs from your field, each with a known-good answer, built with your experts. Then the harness that scores against it and the pass marks that decide a release. This is the most valuable two weeks in the project and it happens before any feature is written.
Loading the documents, cutting them by meaning so structure stays whole, embeddings, search by keyword and vector, and reranking. We measure retrieval quality on its own, with recall at k, before the model writes anything. You cannot fix a writing problem that is really a retrieval problem.
Prompt design, tool calling, set-format outputs checked by fixed rules, forced citations, refusal paths and handing over to a human. Everything is improved against the harness, so every change gets a score and is not just argued about.
Routing by difficulty, prompt caching, context sizing, and streaming to make p95 feel faster than it is. Then we run it quietly on real traffic with humans reviewing before anything reaches a customer. We open it up only when the numbers hold.
Traced requests, alerts for odd costs, and thumbs-down feedback sent straight back into the eval set. Every live failure becomes a permanent test, so the same mistake cannot ship twice. Models change under you. The harness is what lets you cope with that.
Every AI system we build has a clear budget for correctness, speed and cost. We agree it with you before the build and use it as a pass mark for release. "It seems pretty good" is not a launch rule we accept.
Talk about your use caseReal inputs from your field, labelled by experts
Streaming, with retrieval in the path
Routing by difficulty, reranking, caching
Or a clear, honest refusal
Contracts, policies, tenders, technical manuals, claim files. Answers to questions based on the documents, with citations the reader can open. Clauses pulled into set fields, and comparison across versions. This is where RAG truly pays off, and where careless chunking quietly ruins everything by cutting a table in half.
Answers based on your help centre and order data, with a way to refuse and a clean handover to a human. Fewer tickets is measured honestly, against problems solved, not against "did not open a ticket".
Ticket routing, invoice and KYC extraction, lead scoring, defect detection. Often a small trained model, not an LLM. It is faster, cheaper and more accurate, and we will say so.
Demand forecasting, spotting customers likely to leave, changing prices with demand, and suggesting the next best step. Real ML tested on past data, not a chatbot wearing a lab coat.
Tool-calling systems that read a document, query a database, draft an action, and stop for a human where money or risk changes hands. We keep them narrow on purpose. A broad agent that acts alone is a demo. A narrow one that matches three hundred invoices a day and flags the eleven it is unsure about is a product.
Top models change every three months. The harness, the retrieval layer and the guards are what last. So we build in a way that lets you swap the model in an afternoon.
Systems that are measured, not just shown in demos.
A fleet, ePOD and route-planning platform that works offline first, for drivers on roads with poor signal. The two ready-made TMS products t...
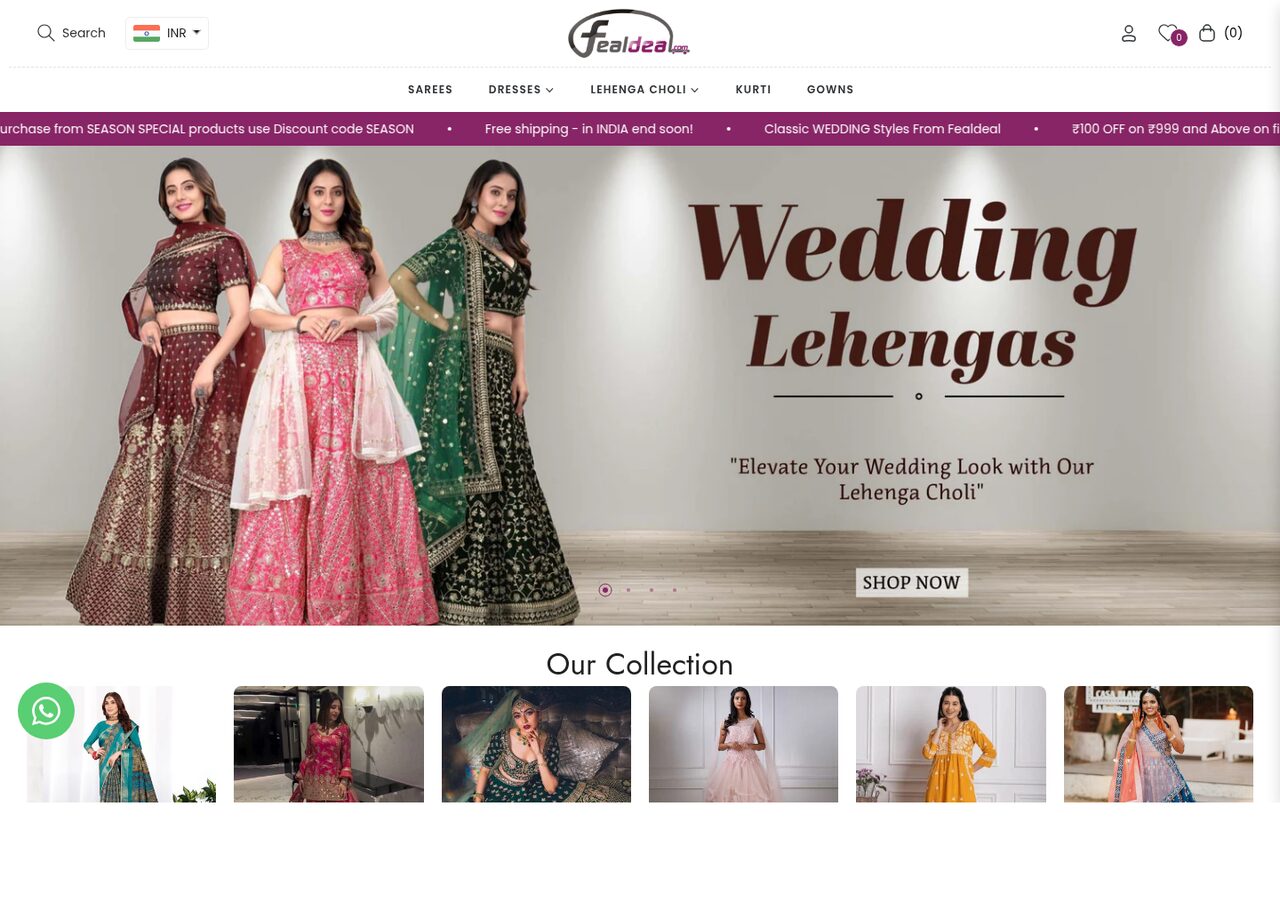
A Shopify store for a Surat ethnic-wear label. It has 200+ SKUs of lehengas, sarees and suits, sorted by type, colour, fabric and work. Shop...
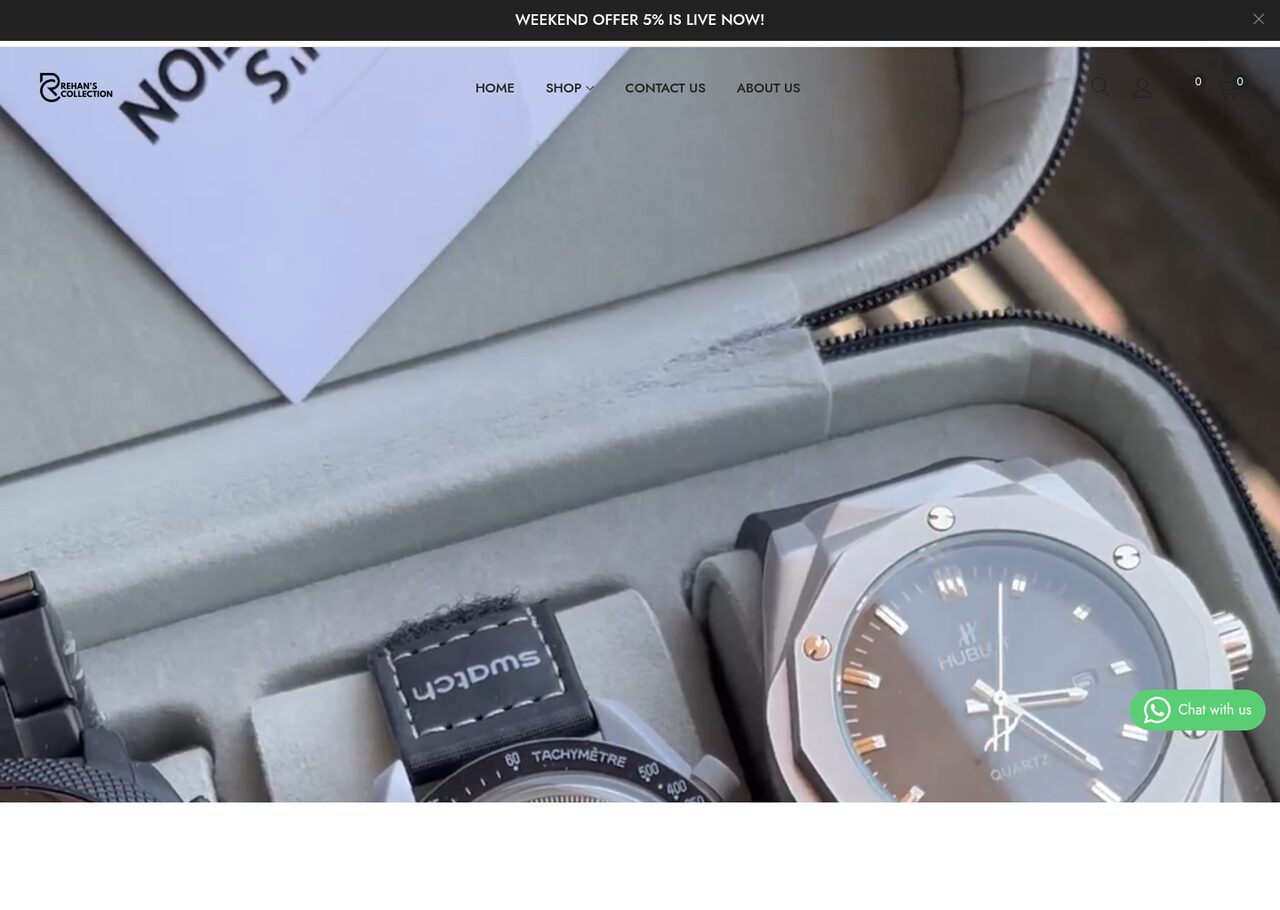
A Shopify storefront for a Surat watch and eyewear retailer — where shoppers can browse by gender, brand, style and combo. It has search tha...
Sometimes the answer is a two-week classifier instead of a six-month AI programme. You will get that answer straight, and for free, in the first conversation.
Proof
Swasthya Sarathi
A website and mobile app development project for a multi-service healthcare companion — It helps peo...
Read itMV Tech Education
A website development project for a Bihar vocational institute. It is a course list and admissions s...
Read itPatna Taxi
A website development project for a Patna and Muzaffarpur cab operator. It is a fast taxi-booking si...
Read itLive web applications built on Laravel, Next.js and Postgres. They are typed, tested, easy...
ExploreFlutter, React Native and native apps that keep working offline, on old phones and on a me...
ExploreCommerce platforms where the checkout turns visits into sales and the back office numbers...
ExploreLet's talk ai & ml development
A senior engineer reads every enquiry. You'll get a real answer — scope, risk and a number — within one business day.